The media infrastructure behind your best work.
Image, video, and audio APIs built for teams that generate at scale.
curl https://api.segmind.com/v2/seedance-2.5 \ -H "x-api-key: $SEGMIND_API_KEY" \ -d '{"prompt": "neon market, slow dolly"}'- models
- 550+
- API key
- 1
- pricing
- Pay as you go
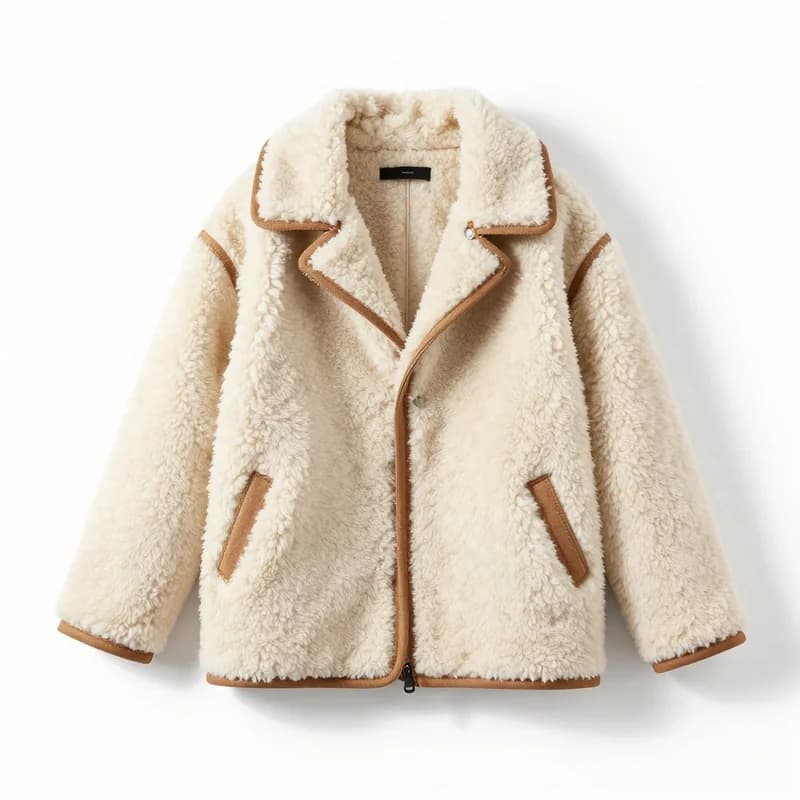
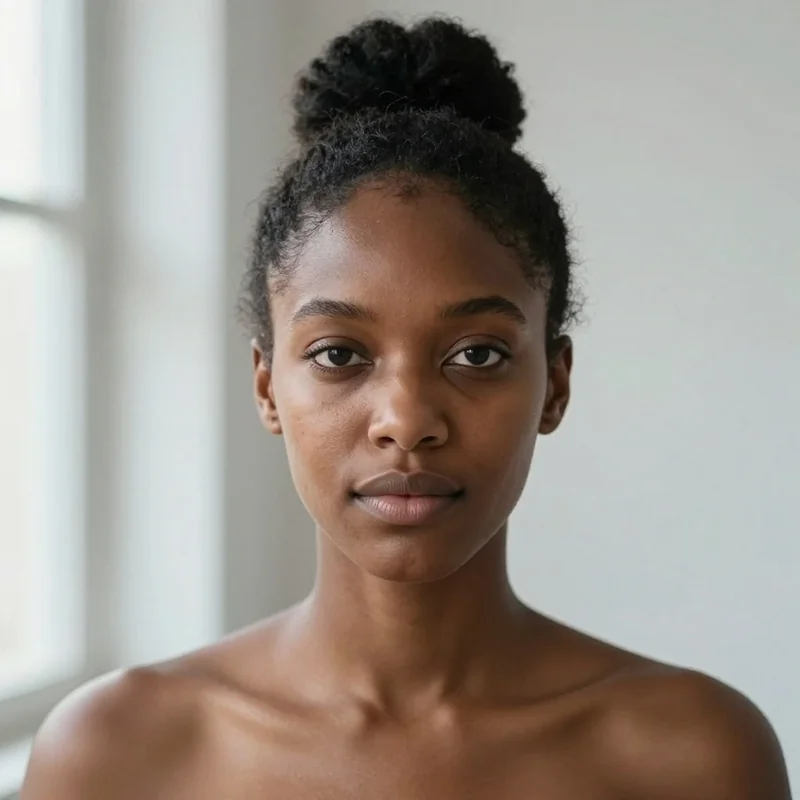
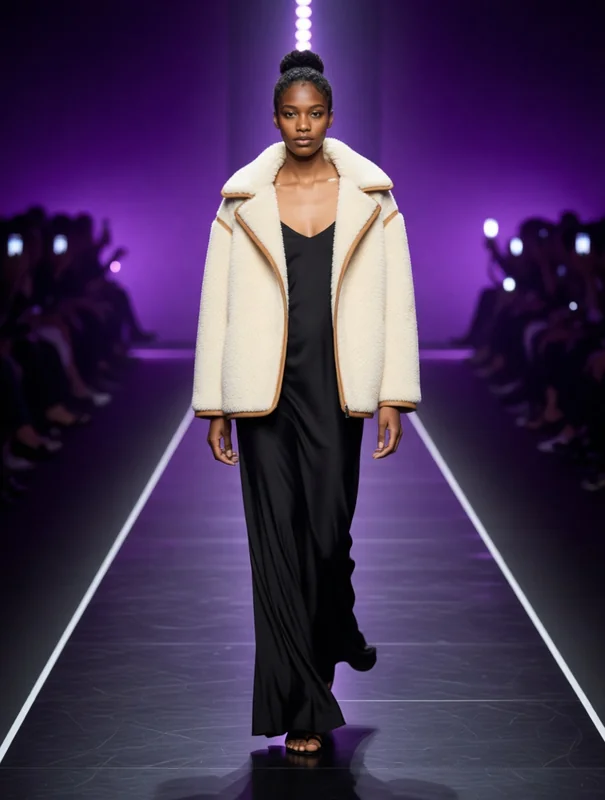
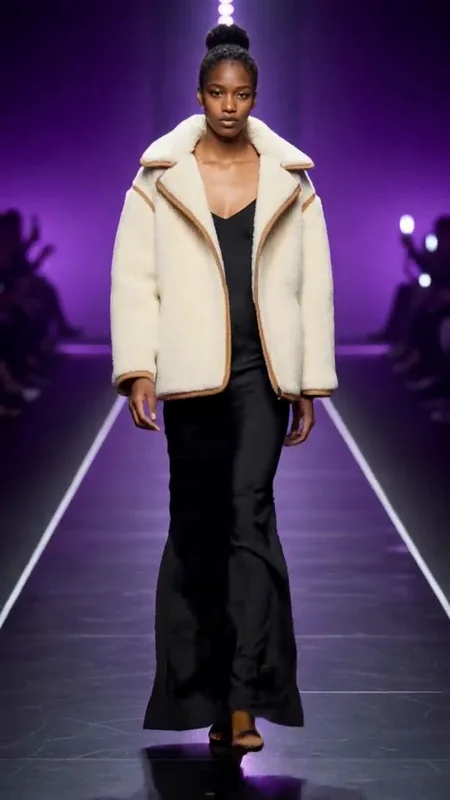
Animated example: reference images and generated voice lines run through image, speech and video models in a Pixelflow graph.
The model library
Every model your best work needs, on one shelf.
The newest image, video and audio models land here first, behind one API key and one bill. Call any of them from your code, or chain them into a Pixelflow workflow.
Showing 100 models
Pixelflow · real world use cases
Chain them into the work you actually ship.
Teams run these pipelines in production. What goes in, which models run, what comes out.
Catalog
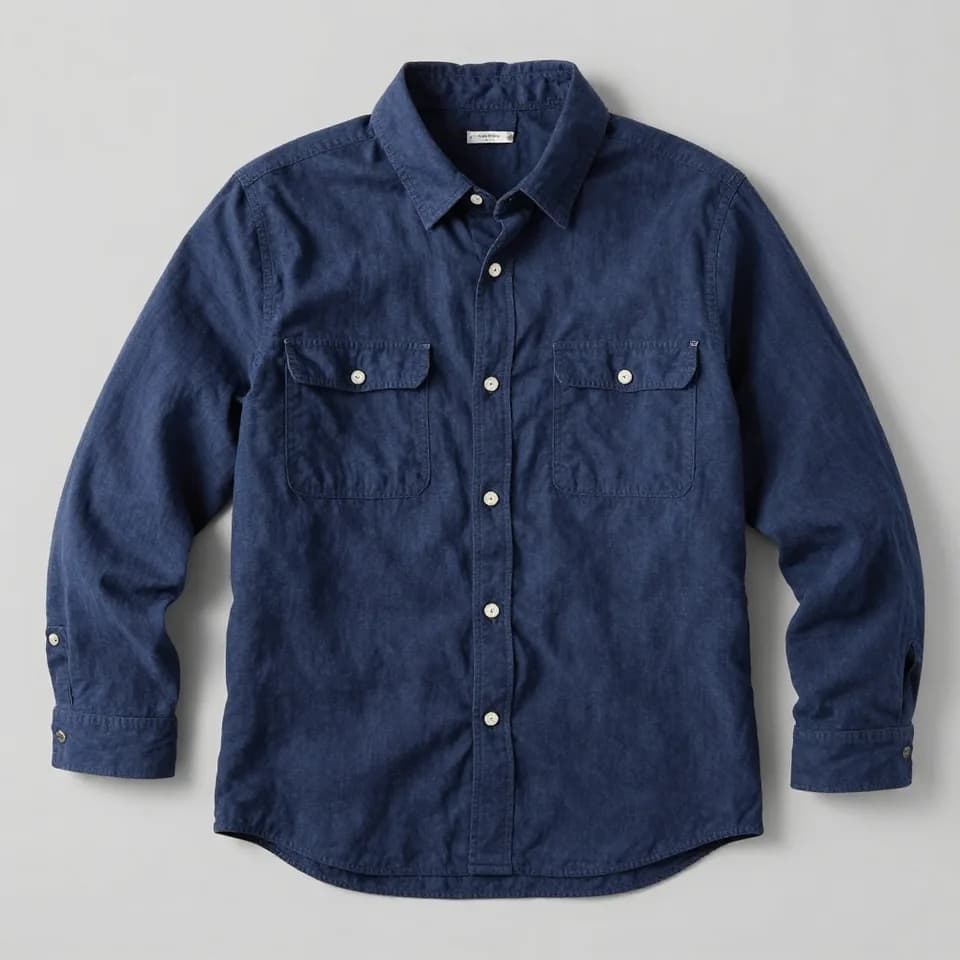
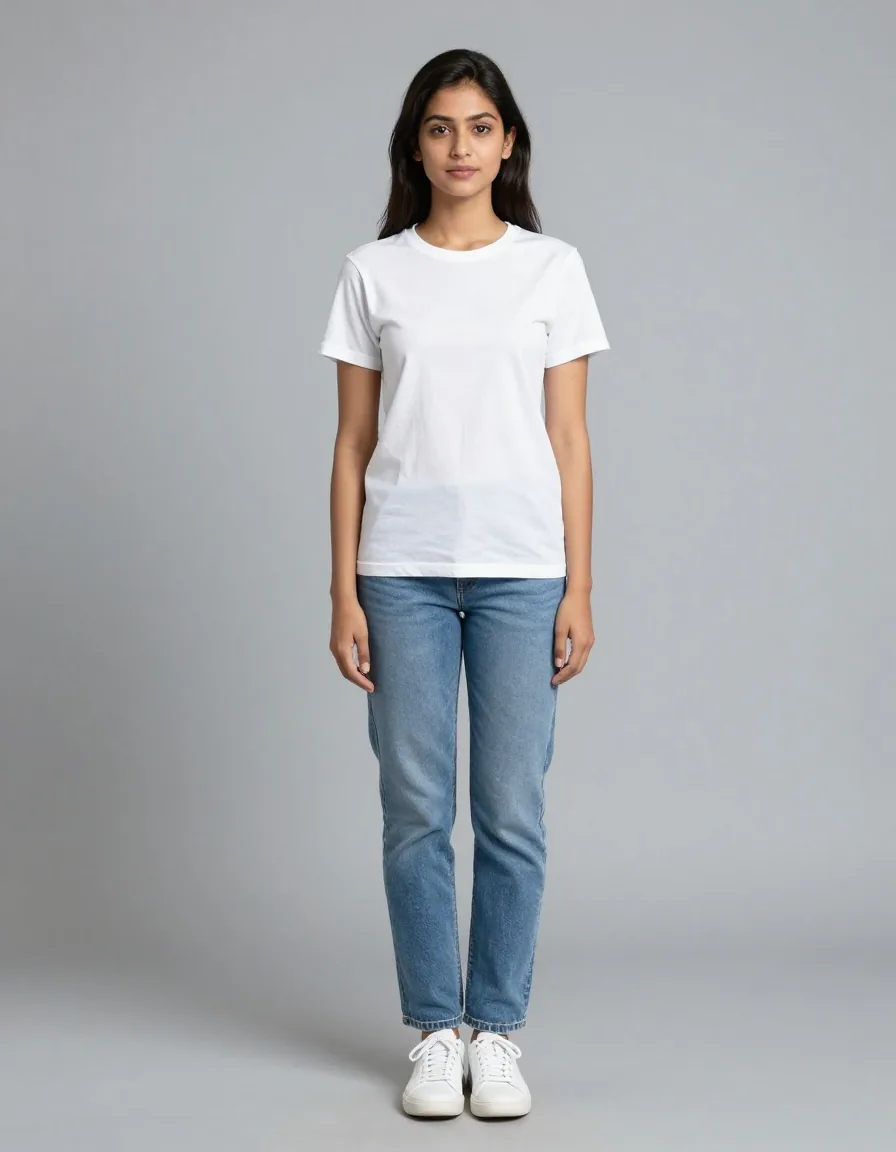
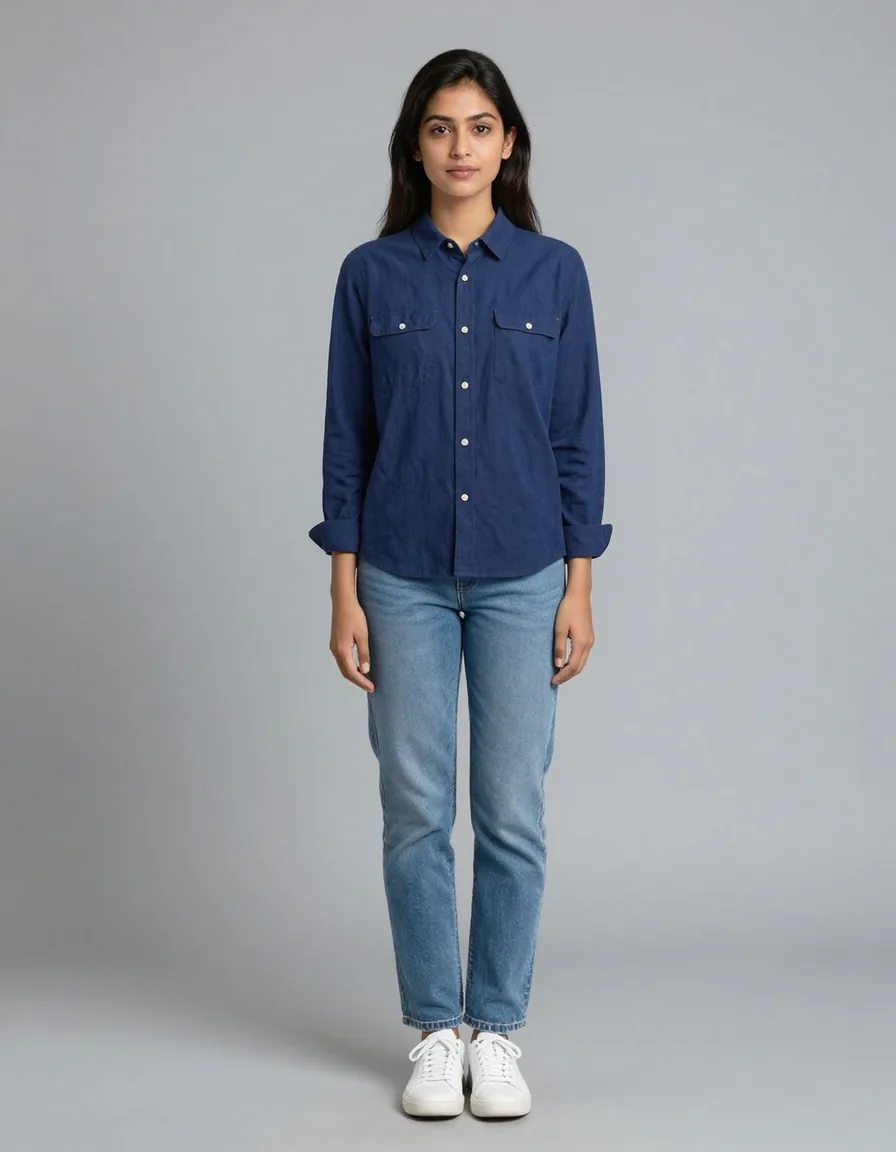
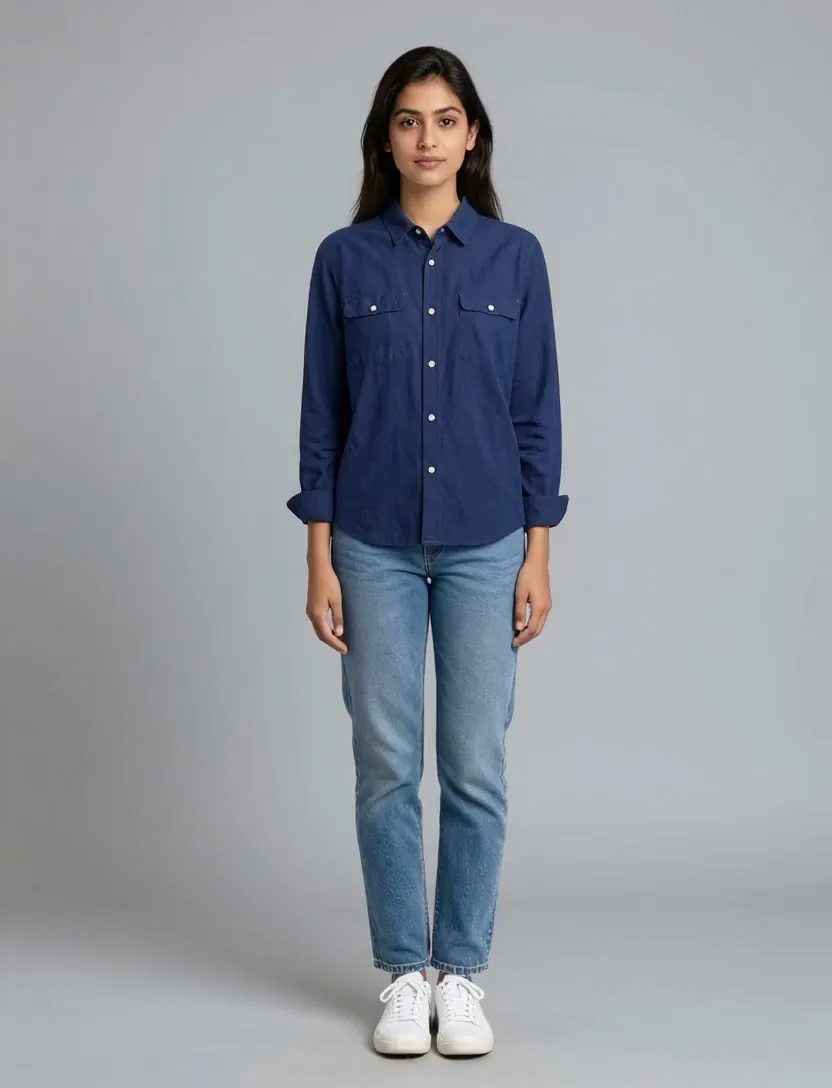
One flat-lay, a whole catalog.
Pixelflow reads the garment, writes the listing, dresses it on a model and films the turn, for every SKU in the drop.
Explore catalog flowsAdapt
One launch, every screen.
Start from one key visual. Pixelflow recomposes it for stories, feeds and billboards, so a launch ships in every format on the same day.
Explore adapt flowsLocalize
One ad, every language.
Translate the script, re-voice it and re-sync the lips, so a spot shot once in English airs in Hindi, Spanish and beyond.
Explore localize flowsStoryboard
One line of script to a finished shot.
Lock the character once, generate every shot around it and animate the keeper. Studios run whole series this way.
Explore storyboard flowsPersonalize
Every fan, in the trailer.
A selfie in, a personal scene out. One flow renders a version for every fan, with no shoot and no editor in the loop.
Explore personalize flows
Featured Models
Explore What's Possible. Dive into the models redefining AI.
ChatGPT Image 1.5
Pure Vision. 4× Faster.
Native multimodal transformer with surgical region editing, OCR-native text rendering, and deterministic output.
Explore
HappyHorse 1.0
Cinema. In Every Language.
Alibaba's flagship video model. 1080p with native audio, 7-language lip-sync, multi-shot up to 15s. Built to challenge Seedance 2.0.
Explore
Seedance 2.0
Cinema in Every Frame.
The first unified multimodal director — text, image, audio, and video synthesised in a single seamless pass.
Explore
Seedream 5.0 Lite
Visual Intelligence. Not Just Synthesis.
The first image engine that reasons through physics, space, and real-world logic. 3K results in 30 seconds.
ExploreBuilt on the Brilliance of the World's Top AI Models
Segmind connects you to breakthrough models from our partners across the Gen AI landscape. It's your launchpad for limitless creation.

 Alibaba
Wan 3.0 Video Prime
Fast 30-second 1080p video with native audio and lip-sync.
Wan 3.0 Video
Generate 30-second 1080p video with native audio.
Wan 2.6 Image to Video Flash
Animate photos into 15-second 1080p video with native audio.
Qwen Image 3.0
Generate and edit legible in-image text, up to 2K.
Wan 3.0 Video Prime
Fast 30-second 1080p video with native audio and lip-sync.
Wan 3.0 Video
Generate 30-second 1080p video with native audio.
Wan 2.6 Image to Video Flash
Animate photos into 15-second 1080p video with native audio.
Qwen Image 3.0
Generate and edit legible in-image text, up to 2K.
HappyHorse 1.1
Generate cinematic video with synchronized native audio and multilingual lip-sync from text, an image, or reference images.
HappyHorse 1.0
Cinematic 1080p text-to-video with native audio and lip-sync.

 Kling
Kling O3 Image To Video
Images to cinematic videos with precise motion control.
Kling O3 Video To Video Edit
Text-based video editor — swap backgrounds, characters, restyle scenes.
Kling V3 Image 2 Image
Transform images into photorealistic, production-ready visuals.
Kling V3 Text to Image
Photorealistic, print-ready images from text prompts.

 Black Forest Labs
Flux 2 Max
Photorealistic images with maximum consistency and fine detail.
Flux 2 Flex
Consistent-style photorealistic images using reference inputs.
Flux 2 Max
Photorealistic images with maximum consistency and fine detail.
Flux 2 Flex
Consistent-style photorealistic images using reference inputs.

 Bria
Bria Ad Delayer
Decompose flat ads into editable JSON layers.
Bria Extract Object
Extract any named object into a transparent PNG cutout.
Bria Ad Delayer
Decompose flat ads into editable JSON layers.
Bria Extract Object
Extract any named object into a transparent PNG cutout.

 ElevenLabs
 Music
Generate full songs with vocals or instrumental from text.
TTS Elevenlabs With Timing
Emotionally expressive TTS with word-level timestamp output.
ElevenLabs Music
Generate full songs with vocals or instrumental from text.
TTS Elevenlabs With Timing
Emotionally expressive TTS with word-level timestamp output.

 Google
Gemini 3.8 Flash-Lite TTS
Expressive multilingual text-to-speech with two-speaker dialogue.
Gemini 3.8 Flash TTS
Direct expressive text-to-speech with two-speaker dialogue, 130+ languages.
Gemini Omni 1.1
Text-to-video with synchronized native audio, up to 4K.
Gemini Omni 1.1 Video Extend
Extend short video clips into longer seamless scenes.
Gemini Omni 1.1 Video Edit
Edit videos with a text prompt, subject preserved.
Lyria 3 Pro
Full-length text-to-music songs with vocals and lyrics.

 OpenAI
GPT Image 2.5 Sunburst
Precisely edit and generate images with legible in-image text.
GPT Image 2.5 Flare
Fast text-to-image and editing with legible in-image text.
Whisper Large V3
Transcribe speech-to-text in 99 languages with timestamps.
GPT Image 2
Generate photorealistic images with legible multilingual text and 2K output.

 Meta
Sam Audio Large
Isolate any described sound from mixed audio tracks.
Sam 3D Object
Single 2D image into detailed 3D object models.
Sam Audio Large
Isolate any described sound from mixed audio tracks.
Sam 3D Object
Single 2D image into detailed 3D object models.

 Ideogram
 4.5 Edit
Precise image editing with masks, references, and legible text.
Ideogram 4.5
Render exact in-image text and multilingual typography for designs.
Ideogram 4.5 Edit
Precise image editing with masks, references, and legible text.
Ideogram 4.5
Render exact in-image text and multilingual typography for designs.

 Bytedance
ModelArk Artifact Verification
Detect Seedance and Seedream AI-generated images and video.
Seedance 2.5 Draft Final
Finalize 480p drafts to 1080p video with native audio.
ModelArk Artifact Verification
Detect Seedance and Seedream AI-generated images and video.
Seedance 2.5 Draft Final
Finalize 480p drafts to 1080p video with native audio.
Frequently asked questions
Reach out to our founders anytime.
Get in touch