Segmind-VegaRT - Latent Consistency Model (LCM) LoRA of Segmind-Vega
Segmind-VegaRT a distilled consistency adapter for Segmind-Vega that allows to reduce the number of inference steps to only between 2 - 8 steps.
Latent Consistency Model (LCM) LoRA was proposed in LCM-LoRA: A universal Stable-Diffusion Acceleration Module by Simian Luo, Yiqin Tan, Suraj Patil, Daniel Gu et al.
This model is the first base model showing real-time capabilities at higher image resolutions, but has its own limitations;
- •
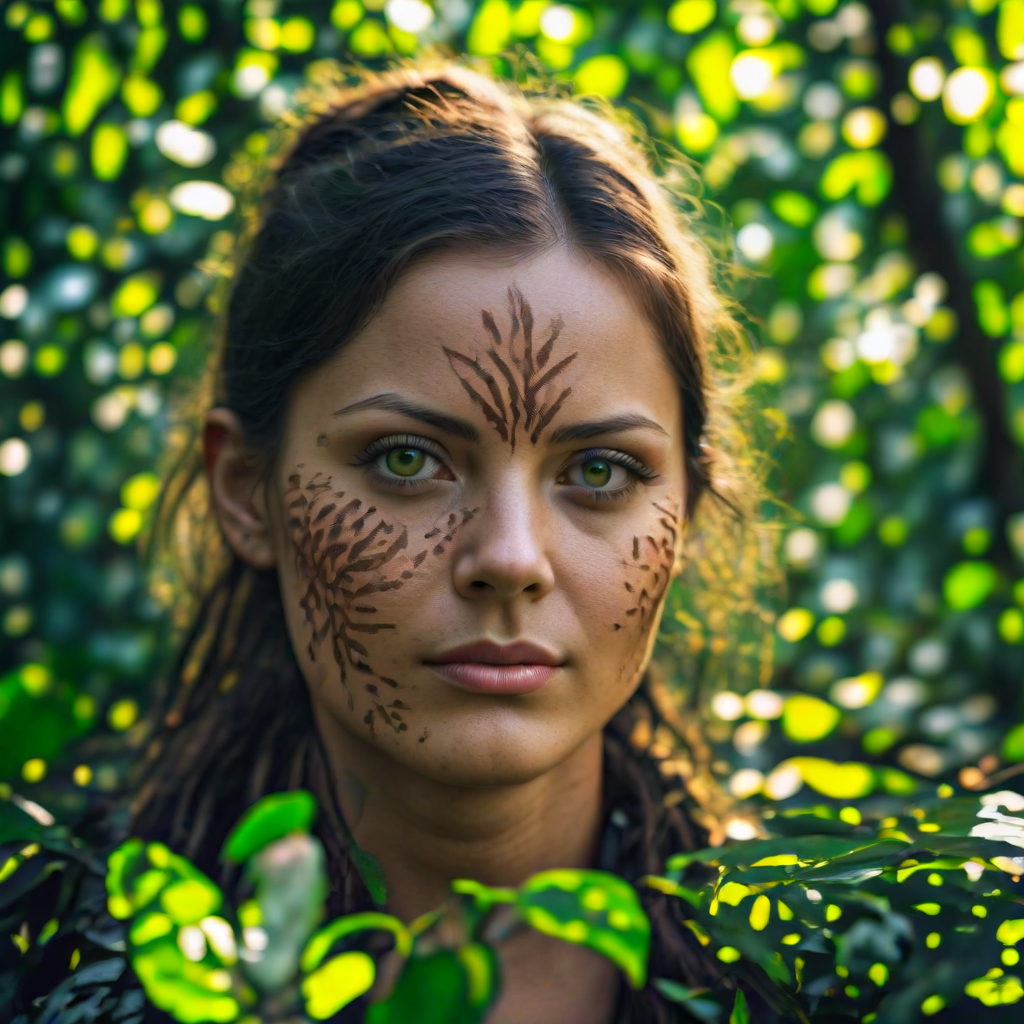
The model is good at close up portrait images of humans but tends to do poorly on full body images.
- •
Full body images may show deformed limbs and faces.
- •
This model is an LCM-LoRA model, so negative prompt and guidance scale parameters would not be applicable.
- •
Since it is a small model, the variability is low and hence may be best used for specific use cases when fine-tuned.
We will be releasing more fine tuned versions of this model so improve upon these specified limitations.